Author: SEOScanPRO

  • Claude Sonnet 5 Ships as Anthropic Joins a Week of AI Policy Crossroads

    Claude Sonnet 5 Ships as Anthropic Joins a Week of AI Policy Crossroads

    Anthropic released Claude Sonnet 5 this week as a lower-cost, faster counterpart to Opus 4.8, framing it as a measured upgrade rather than a generational leap. The release itself drew modest attention, while the surrounding week, dominated by constitutional arguments, an open-weight policy push, and new commentary on frontier safety norms, raised far more questions about what site owners, developers, and auditors should track next.

    What the Sonnet 5 release means in practice

    Sonnet 5 lands as a smaller increment than the version bump implies, and testers are still benchmarking it across coding, long-context retrieval, and reasoning tasks. For technical teams, the practical questions concern cost ceilings, context window behavior, and how it slots into existing pipelines that already assume Sonnet 4 class output. Until third-party evals stabilize, treat vendor claims with the same skepticism you would apply to any new model card.

    Open-weight releases are the policy fault line auditors should watch

    Open-weight frontier releases, meaning models shipped with openly licensed weights that anyone can download and run, sit at the center of the week’s regulatory debate. The argument against them is straightforward: once weights are out, they cannot be recalled, so safety depends on decisions made before publication rather than after. Critics tend to mix two distinct claims, that publication is itself unsafe and that downstream misuse is inevitable, and those claims have different policy remedies.

    Banning the publication of model weights creates a separate First Amendment problem, because courts may eventually treat the weights themselves as expressive material. Export controls and proliferation rules operate under different statutory authority, so a serious response needs to address both the speech dimension and the proliferation dimension separately. Any site or product owner using open-weight models should map which jurisdictional regime covers their deployment: hosting location, distribution channel, and downstream user geography each pull the model into different compliance buckets.

    How Slaughter v. Trump reshapes the regulatory architecture

    The Supreme Court’s 6-3 decision in Slaughter v. Trump overruled Humphrey’s Executor and lets the President remove officers at most independent agencies for any reason. The Federal Reserve is the documented exception for historical reasons. For AI, the chain of effects runs through any proposed Frontier AI Commission with powers to license training runs, compel evaluations, restrict deployments, order pauses, or impose penalties. Under the new precedent, commission leaders would be removable at the President’s discretion, which makes an independent expert body much harder to design through ordinary legislation.

    Two readings are now in play. One treats the ruling as an acknowledgment that agencies like the FTC and SEC have always been political, so the doctrine simply catches up to reality. The other treats even the fiction of nonpartisanship as a useful buffer, one that limits how directly partisan control can be exercised over financial, consumer, and speech regulation. With that buffer weakened, expect more state-level activity, more judicial enforcement routes, and more pressure on platform-level compliance rather than agency-level rulemaking.

    Why the judiciary is becoming the AI policy arena

    Congress has not produced a substantive AI statute, and executive action runs into the limits exposed by Slaughter v. Trump. Courts can move faster and a handful of cases can redirect the entire trajectory. The First Amendment is the most likely vehicle because the strongest legal hook treats frontier AI creation, distribution, and use as protected expression, a step past the older “code is speech” framing.

    If courts accept the full version of the speech argument, the practical effect is not a free-for-all. Governments facing severe risks from unrestricted frontier systems typically shift to the levers that remain: training restrictions, deployment licensing, and physical distribution controls rather than use-based restrictions. If your product roadmap assumes that use-based limits are the only regulatory risk, that assumption is now fragile.

    U.S. versus China frontier regulation

    One striking comparison from the week: the United States currently restricts its own frontier AI more than China restricts Chinese frontier systems. That is not a permanent state of affairs. When the U.S. frontier sat at a comparable capability level, its developers faced far fewer constraints. The pattern suggests that regulation tracks capability rather than jurisdiction. For technical teams building on frontier APIs, plan for the rule set to tighten as model capability rises, regardless of which lab you call.

    The DeepMind Pentagon contract and what it signals about internal leverage

    Commentary on the DeepMind Pentagon contract argues that the agreement was signed with language broad enough to let the government direct how the technology is used. Roughly 600 employees signed an internal letter, and the outcome did not change. Without a credible strike or resignation threat, employee leverage in negotiations like this stays limited. That is the structural argument behind union recognition efforts at DeepMind, which would give staff a formal mechanism to convert stated objections into action.

    For outside teams, the lesson is that published ethics commitments from any AI lab are weaker than binding governance. If your procurement or vendor selection assumes that a lab’s safety culture will block certain government work, that assumption is now demonstrably fragile.

    The AI Incident Reporting Act and capability-based thresholds

    Representative Nate Moran (R-TX) introduced the AI Incident Reporting Act, which keys coverage to a capabilities-based threshold for what counts as a covered model rather than a compute threshold. Capabilities-based definitions are technically harder to write but more durable, since they survive hardware shifts. Preemption in the bill is structured in a way that several legal analysts describe as sound. For auditors, the practical implication is that incident reporting duties may end up tied to model capability assessments you have to perform on your own stack, not to a vendor-published compute number.

    Why the ‘good guy with a gun’ analogy falls short for AI

    The analogy says that if defenders have the same powerful models as attackers, harm is prevented. The premise is weak. Parity is better than attacker dominance, but it still leaves real damage before defenders patch and respond. Historically, attackers faced a talent constraint that limited who would act. If AI lowers the talent required to mount sophisticated operations and the financial incentives remain, that constraint weakens fast. Defensive advantage is not automatic. Optimism about defense winning at the limit depends on active work, better detection, better tools, and policy that gives defenders a head start rather than equal footing.

    What site owners should audit this quarter

    Three concrete checks belong on your next audit cycle. First, map every open-weight or open-source model in your stack to the jurisdiction of its hosting, distribution, and end users, since export-control regimes key off all three. Second, document the capability class of any frontier model you depend on, because capabilities-based thresholds in pending bills will likely make that a reporting trigger. Third, review vendor ethics statements and government contract language for any provider whose outputs reach your users, since the DeepMind case shows that internal commitments did not constrain deployment choices.

    FAQ

    What is Claude Sonnet 5 and how does it compare to Opus 4.8?

    Claude Sonnet 5 is Anthropic’s lower-cost, faster counterpart to Opus 4.8, released this week as a relatively incremental update despite the version-number jump. Independent testers are still forming a clear picture of how it performs across coding, reasoning, and long-context tasks.

    Why does Slaughter v. Trump matter for AI policy?

    The Supreme Court ruled 6-3 in Slaughter v. Trump to overrule Humphrey’s Executor, letting the President fire officers at most independent agencies for any reason. A Frontier AI Commission with powers such as licensing training runs, restricting deployments, or ordering pauses would have leaders removable at the President’s discretion, making independent expert bodies harder to build through ordinary legislation.

    Could frontier AI models be treated as protected speech?

    Legal thinkers are beginning to argue that frontier AI creation, distribution, and use should be treated as protected expression under the First Amendment, going beyond the older “code is speech” framing. Critics note that if courts accepted this fully, the natural government response would shift to restricting the training, deployment, and physical distribution of sufficiently capable models rather than how they are used.
    Related coverage

  • What Cursor’s Native iOS Build Reveals About AI-Assisted Mobile Development

    What Cursor’s Native iOS Build Reveals About AI-Assisted Mobile Development

    Cursor’s engineering team built a native iOS companion to its AI-powered code editor using that same editor as the primary development tool, according to a write-up on the Cursor blog. The project leaned on the assistant for SwiftUI scaffolding, refactoring, and debugging rather than for isolated snippets, treating the model as a collaborator across the full lifecycle of the app. The team picked a native build to deliver a responsive, platform-specific experience for developers who need to review changes, answer questions, and make small edits away from their main workstation.

    For teams evaluating how AI fits into a real production codebase, especially one targeting a platform their developers rarely touch, this case study carries a few audit-ready signals worth checking against your own workflows.

    Why a native iOS companion, and why now

    Cursor had previously concentrated its editor on desktop platforms. The mobile companion extends that surface area into the moments developers actually have a phone in hand: reviewing a pull request, answering a reviewer’s question, or shipping a small fix without booting a laptop. Choosing a native build, rather than a cross-platform wrapper, gives the team access to platform-specific affordances and keeps the interaction model responsive on real iOS hardware.

    That choice also shapes what an AI assistant has to understand. A cross-platform framework would let a model lean on familiar patterns from web or React backgrounds; a native SwiftUI codebase forces the assistant to work inside Apple’s API surface, which fewer developers carry in muscle memory. So the build doubles as a stress test for how well current coding models handle a less-common stack.

    What the engineering team actually delegated to the assistant

    The write-up describes AI involvement at several layers of the project, not just at the prompt-and-paste stage. Engineers used the assistant to:

    • Produce boilerplate and scaffolding for SwiftUI views and view models.
    • Translate rough sketches and mental models into working interface code.
    • Refactor existing modules so they could be reused across multiple screens.
    • Debug tricky layout and state issues that would normally require patient manual inspection.

    That spread matters for anyone auditing their own AI usage. It shows the assistant operating across the full range of mobile tasks: UI scaffolding, architecture-level refactoring, and low-level state debugging. Each of those has a different failure mode if the generated code is accepted without review.

    Patterns worth checking on your own codebase

    Three habits from the team’s workflow translate cleanly into audit checks for any AI-assisted project.

    1. Define the target before the prompt

    The team started with a well-scoped feature set and a clear sense of which screens carried the most weight. That pre-work made it easier to point the assistant at productive tasks instead of open-ended ones. On a real codebase, the audit equivalent is a short written brief per task: which file, what behavior, what acceptance test. Without that, the model tends to drift toward plausible-looking but loosely scoped output.

    2. Iterate in small, runnable units

    Rather than asking the assistant to produce large monolithic files, the engineers worked in smaller pieces that could be reviewed and run quickly. The audit angle here is commit hygiene. Small AI-generated diffs are easier to read, easier to revert, and easier to attribute if a regression shows up later. Large generated drops tend to obscure which prompt produced which line.

    3. Keep human reviewers in the loop on architecture and naming

    The write-up emphasizes that architecture, naming, and the final shape of the code still come from human judgment. The assistant is most useful when paired with engineers who understand the platform underneath. That maps to a concrete review checklist: who signed off on the module boundaries, who validated the naming conventions, and who confirmed the generated code matches the patterns already established in the rest of the codebase.

    What this says about the current state of AI coding tools

    Shipping a full mobile application is a serious workload for any coding assistant. It spans UI work, platform integration, networking, state management, and ongoing iteration after the first release. Cursor’s experience suggests current tools can meaningfully accelerate that workload when the engineer using them already understands the underlying platform.

    It also reinforces a pattern visible across recent developer surveys: AI tools deliver the most value on tasks that are well understood and repetitive, freeing engineers to spend their attention on design decisions and edge cases that demand deeper context. Tasks that require deep platform knowledge, custom business logic, or tricky debugging still benefit from an experienced engineer steering the model.

    How to audit an AI-assisted mobile build

    If your team is shipping an iOS or Android app with heavy AI assistance, a few targeted checks will surface most of the risk.

    • Trace generated code back to the prompt that produced it. If that trail is missing, the team cannot tell which instruction led to a regression.
    • Look for inconsistent architectural patterns between AI-generated files and human-written files. Mixing two styles is a common signal that review was light.
    • Confirm that platform-specific assumptions (such as concurrency models, lifecycle handling, and permissions) match Apple’s current guidance rather than older API snapshots that the model may have learned.
    • Check that state management across screens uses a single source of truth. AI assistants will happily invent parallel state stores if the brief is not explicit.
    • Measure review latency on AI-generated pull requests versus human-written ones. A wide gap often indicates reviewers are skipping the deeper passes.

    What the app itself signals

    The Cursor iOS app reflects the team’s working philosophy: a quick, low-friction interface for interacting with code and AI assistance while away from a full development environment. The fact that the team felt confident enough to put its own assistant in front of paying users in a mobile context is, in itself, a vote of confidence in the current generation of AI coding tools. It does not mean those tools are ready to run unsupervised. It means a skilled engineering team can ship a real product with them, which is a different and more useful claim.

    For anyone weighing how to bring AI tooling into a production codebase, especially one targeting a less familiar platform, the full engineering write-up on the Cursor blog is worth reading alongside your own audit checklist.

    FAQ

    What is the Cursor iOS app?

    The Cursor iOS app is a native mobile version of Cursor’s AI-powered code editor, built by Cursor’s engineering team so developers can review changes, respond to questions, and make small edits away from their main workstation.

    What did the Cursor team use its AI assistant for during the iOS build?

    Engineers used Cursor’s own AI assistant to generate SwiftUI boilerplate, turn sketches into working interface code, refactor reusable modules across screens, and debug layout and state issues, treating the assistant as a collaborator rather than a one-off snippet generator.

    How should a team audit an AI-assisted mobile codebase?

    Useful checks include tracing generated code back to the prompts that produced it, flagging inconsistent architectural patterns between AI and human-written files, confirming platform-specific code matches current Apple guidance, enforcing a single source of truth for state, and measuring review latency on AI-generated pull requests.

  • Meituan Says LongCat-2.0 Ran End-to-End on Chinese Chips: What Site Owners Should Watch

    Meituan Says LongCat-2.0 Ran End-to-End on Chinese Chips: What Site Owners Should Watch

    Meituan released LongCat-2.0, a 1.6-trillion-parameter open-weight language model, and the headline is not the parameter count. It is the hardware story. The company says it both pre-trained and served the model on a 50,000-chip cluster of domestically developed Chinese accelerators, with no Nvidia silicon involved in the heavy lifting. If independent testing backs that up, LongCat-2.0 becomes the largest model publicly shown to complete the full training pipeline on chips built in China, and a direct stress test of US export controls.

    Why this matters beyond the AI industry

    For technical SEO auditors and site owners, the news is less about geopolitics and more about what shows up in your stack over the next year. Frontier-scale open-weight models from non-US providers change three things at once: the cost of running a private inference endpoint, the latency you can expect from a self-hosted setup, and the diversity of providers you can negotiate with. A model trained without American hardware also signals that the supply of capable weights is decoupling from a single country’s chip policy, which affects long-term pricing and availability.

    What the announcement actually claims

    Meituan published LongCat-2.0 with a one-million-token context window and said its benchmark performance sits near Google Gemini 3.1 Pro, released in February. The company described it as the first trillion-parameter model to finish both training and inference on a 50,000-chip domestic cluster, and released the weights openly so anyone can load the model and reproduce the benchmark results themselves. The end-to-end framing is the load-bearing word. Many Chinese models already run inference on local hardware; the expensive stage is pre-training, where a model absorbs its training corpus, and that is where access to top-tier accelerators has mattered most.

    The numbers to pin down

    • 1.6 trillion parameters, on par with the largest open-weight systems publicly announced.
    • 1,000,000-token context window, long enough for full-document and long-session workloads.
    • 50,000-chip domestic cluster used for what Meituan calls full training and serving.
    • Open weights released alongside the announcement, so benchmark claims are testable.
    • Comparable to Gemini 3.1 Pro on the benchmarks Meituan chose to cite.

    What an auditor should actually check

    When a new open-weight model lands, the temptation is to swap it into a production pipeline on day one. A more disciplined checklist looks like this:

    • Verify the weights and license. Confirm the release on a trusted mirror and read the license file. Open-weight does not automatically mean permissive; some releases restrict commercial use or require attribution.
    • Reproduce the cited benchmarks on your own hardware. Vendor benchmark numbers are usually the best-case runs. Run the same suites on the GPU you plan to deploy on and compare latency, tokens-per-second, and quality on your own prompt distribution.
    • Audit the training-data disclosure. For SEO content work especially, you want to know whether scraped web pages are in the training set, because that affects how the model treats copyrighted material and brand mentions.
    • Test context-length behavior at the edge. A one-million-token window on paper often degrades past 200,000 tokens. Benchmark the upper end before you promise long-document summarization to clients.
    • Map the supply chain for the inference hardware. If the model only performs well on a specific accelerator family, factor that into your hosting cost and vendor lock-in analysis.

    How independent verification is likely to play out

    Reproducing benchmark scores is straightforward once weights are public. Reproducing the training-hardware claim is much harder, because it depends on Meituan’s own logs, cluster configuration, and tooling. Expect the open-source community to confirm or push back on the quality claims within weeks, but treat the end-to-end-on-domestic-chips framing as a company statement until a third party audits the training run, which may never happen publicly. Watch for replication attempts from academic labs and from competitors such as Alibaba’s T-Head unit, which is promoting its own Zhenwu M890 accelerator. Multiple independent training runs on Chinese silicon would matter far more than a single claim.

    What this means for the open-weight market

    Open-weight releases at this scale compress the price of frontier capability. If LongCat-2.0 holds up, a site owner evaluating a self-hosted model for content generation, classification, or log analysis now has a fourth or fifth serious option beyond the familiar US names, and the cheapest viable option may come from an unexpected source. For agencies and in-house teams running technical SEO audits, the practical move is to keep a short list of open-weight candidates, refresh it each quarter, and re-benchmark whenever a release lands, rather than locking in a single provider for a multi-year contract.

    FAQ

    What is LongCat-2.0?

    LongCat-2.0 is a 1.6-trillion-parameter language model released by Meituan with a one-million-token context window. Meituan says its benchmark performance is comparable to Google Gemini 3.1 Pro and has released the weights as open source.

    Why does training on domestic Chinese chips matter?

    Pre-training is the most compute-intensive stage of building a model and the step where access to top accelerators has historically been the bottleneck. Finishing pre-training and inference on a 50,000-chip domestic cluster would show that a frontier-scale model can be built without US hardware, which is the outcome US export controls were designed to prevent.

    How can a site owner verify the claim?

    You can download the open weights and run the benchmark suites Meituan cites on your own hardware to check the quality claim. The training-hardware claim is harder to verify from outside, since it depends on Meituan’s internal infrastructure logs, so treat it as a company statement until an independent party publishes a replication.

    Related coverage

  • Government-Vetted Trusted Partners Get GPT-5.6 First: What the Restricted Rollout Means for Technical Audits

    Government-Vetted Trusted Partners Get GPT-5.6 First: What the Restricted Rollout Means for Technical Audits

    OpenAI confirmed on Friday that its GPT-5.6 series will not ship to the general public on launch day. The three new models, Sol, Terra, and Luna, are being distributed through a limited preview shared with a government-vetted group of trusted partners, with general availability expected in the coming weeks. The arrangement marks the first time a flagship ChatGPT release has been staggered at the administration’s explicit request, and it follows the export control directive that disabled Anthropic’s Fable 5 and Mythos 5 days after they went public earlier in June.

    What changed about how GPT-5.6 is being released

    Every prior ChatGPT generation, from GPT-3 through the GPT-5 family, reached hundreds of millions of users within weeks of launch. GPT-5.6 breaks that pattern. Instead of a synchronized public release, OpenAI has accepted a tiered window in which a credentialed partner group receives the models first while federal reviewers coordinate the broader rollout through the Commerce Department.

    The trigger is a June 2 executive order directing the administration to build a framework for reviewing frontier AI systems before public release. The framework itself is still being drafted, so the Commerce Department is handling the GPT-5.6 launch case by case. OpenAI has framed the trusted-partner preview as a short-term bridge, with general availability expected once the review process stabilizes.

    Why this matters for sites running technical SEO audits

    If your site relies on AI-generated content, AI-powered crawling, or embeddings generated by OpenAI APIs, the assumption of immediate same-day access to a new model is no longer safe. Procurement, staging, and A/B testing timelines need to absorb a trusted-partner window that can stretch from days to weeks before general availability. Documentation, pricing pages, and rate-limit announcements for the new tier have historically lagged the model itself, and that gap is likely to widen when launches are negotiated behind closed doors.

    For audit workflows, that creates several practical checks worth adding to your routine:

    • Verify model version strings in any AI-assisted content pipeline. Pages produced during the trusted-partner window may carry metadata linking to model versions that are not yet documented publicly, which complicates reproducibility and compliance reviews.
    • Track API response headers and changelog feeds for the date a new model actually enters your region or tier. A model that is publicly announced may still be unavailable through your specific endpoint or account class.
    • Document fallback paths in your rendering stack. If a frontier model is gated or pulled mid-cycle, the previous generation becomes the de facto production target, and your schema, canonical tags, and crawl budgets should be tested against that fallback.
    • Re-check structured data and entity markup produced by AI assistants. When a lab updates a model mid-restriction, the underlying knowledge cutoff and naming conventions can shift, which can change how your pages surface in entity-based search results.

    How the GPT-5.6 rollout compares to the Anthropic pattern

    Anthropic’s experience earlier in June is the closest precedent. Fable 5 and Mythos 5 launched publicly, became accessible to all users for three days, and were then disabled after the U.S. government issued an export control directive citing national security concerns. After engagement with authorities, Mythos 5 was partially restored on a limited basis while Fable 5 remained restricted. Commerce Secretary Howard Lutnick wrote to Anthropic co-founder Tom Brown on June 26 acknowledging that the company’s cooperation had produced meaningful progress.

    OpenAI’s approach with GPT-5.6 is structurally different: rather than launch publicly and then pull access, the company started with a trusted-partner preview, avoiding the abrupt disable pattern that hit Anthropic. For developers, both patterns produce the same operational result, which is a tiered access window before general availability, but the OpenAI path is less disruptive to existing production traffic.

    What site owners should monitor while the framework is finalized

    Several signals are worth watching over the next several weeks:

    • Trusted-partner composition. The list of organizations invited into the preview, and the criteria used to select them, will telegraph how the eventual public review framework treats commercial, academic, and government users.
    • General availability timing for Sol, Terra, and Luna. OpenAI has indicated the preview is short-term, but the absence of a hard date means the window could extend if the Commerce Department’s framework slips.
    • Transparency rules in the formal framework. Whether the eventual review process publishes evaluation criteria, timelines, and decision rationales will shape how predictable future launches are for builders.
    • Parallel action at other labs. Google DeepMind and Meta are expected to face similar conversations when they ship next-generation systems, which will test whether the GPT-5.6 and Anthropic patterns become a standard.

    The broader shift in how frontier models reach the market

    Two major U.S. AI labs have now throttled a flagship launch under federal direction during June 2026, and a single June 2 executive order is currently powering the ad hoc review process shaping those release schedules. The era of frictionless, company-timed frontier releases is giving way to staggered, government-coordinated rollouts for the most capable AI systems built on American soil.

    For technical SEO work, the practical implications are concrete. Audit checklists should now include model-version verification, fallback-render testing, and tracking of API availability windows. The websites that hold up best during this transition will be the ones that treat frontier model access as a moving target rather than a fixed dependency, and that build enough redundancy into their AI-assisted pipelines to absorb a delay measured in days or weeks without losing crawl coverage or content consistency.

    FAQ

    Which OpenAI models are affected by the restricted rollout?

    The three models in the GPT-5.6 family, Sol, Terra, and Luna, are currently available only through a limited preview with a government-vetted trusted-partner group, rather than being released to the general public the way previous ChatGPT generations were.

    Why did OpenAI restrict the GPT-5.6 launch?

    OpenAI restricted the rollout at the administration’s request, describing the arrangement as a short-term bridge while the Commerce Department finalizes a formal framework for evaluating frontier AI models under the June 2 executive order.

    How does this compare to the Anthropic situation from earlier in June?

    Anthropic launched Fable 5 and Mythos 5 publicly, then received a federal export control directive three days later and disabled access to both. After cooperation with authorities, Mythos 5 was partially restored while restrictions on Fable 5 remain. OpenAI’s GPT-5.6 approach starting with a trusted-partner preview from the outset avoids the abrupt disable pattern Anthropic experienced.

    Related coverage

  • How to Audit Your Site for Gemini API Computer Use Compatibility

    How to Audit Your Site for Gemini API Computer Use Compatibility

    Google has shipped a computer use feature for the Gemini API that lets developer-built agents read rendered pages as screenshots and click, type, and scroll through a browser. For teams running technical SEO audits, that changes the audit checklist: pages are no longer just crawled by bots, they can now be driven by an agent that interprets pixels and decides the next action. If your site is a candidate target, the questions shift from “can Googlebot parse this?” to “can an agent act on this safely and reliably?”

    The capability is exposed through a dedicated endpoint and is meant to live next to existing function calling and structured output tools. It is aimed squarely at interfaces built for human eyes, which is most public websites.

    What the interaction loop looks like

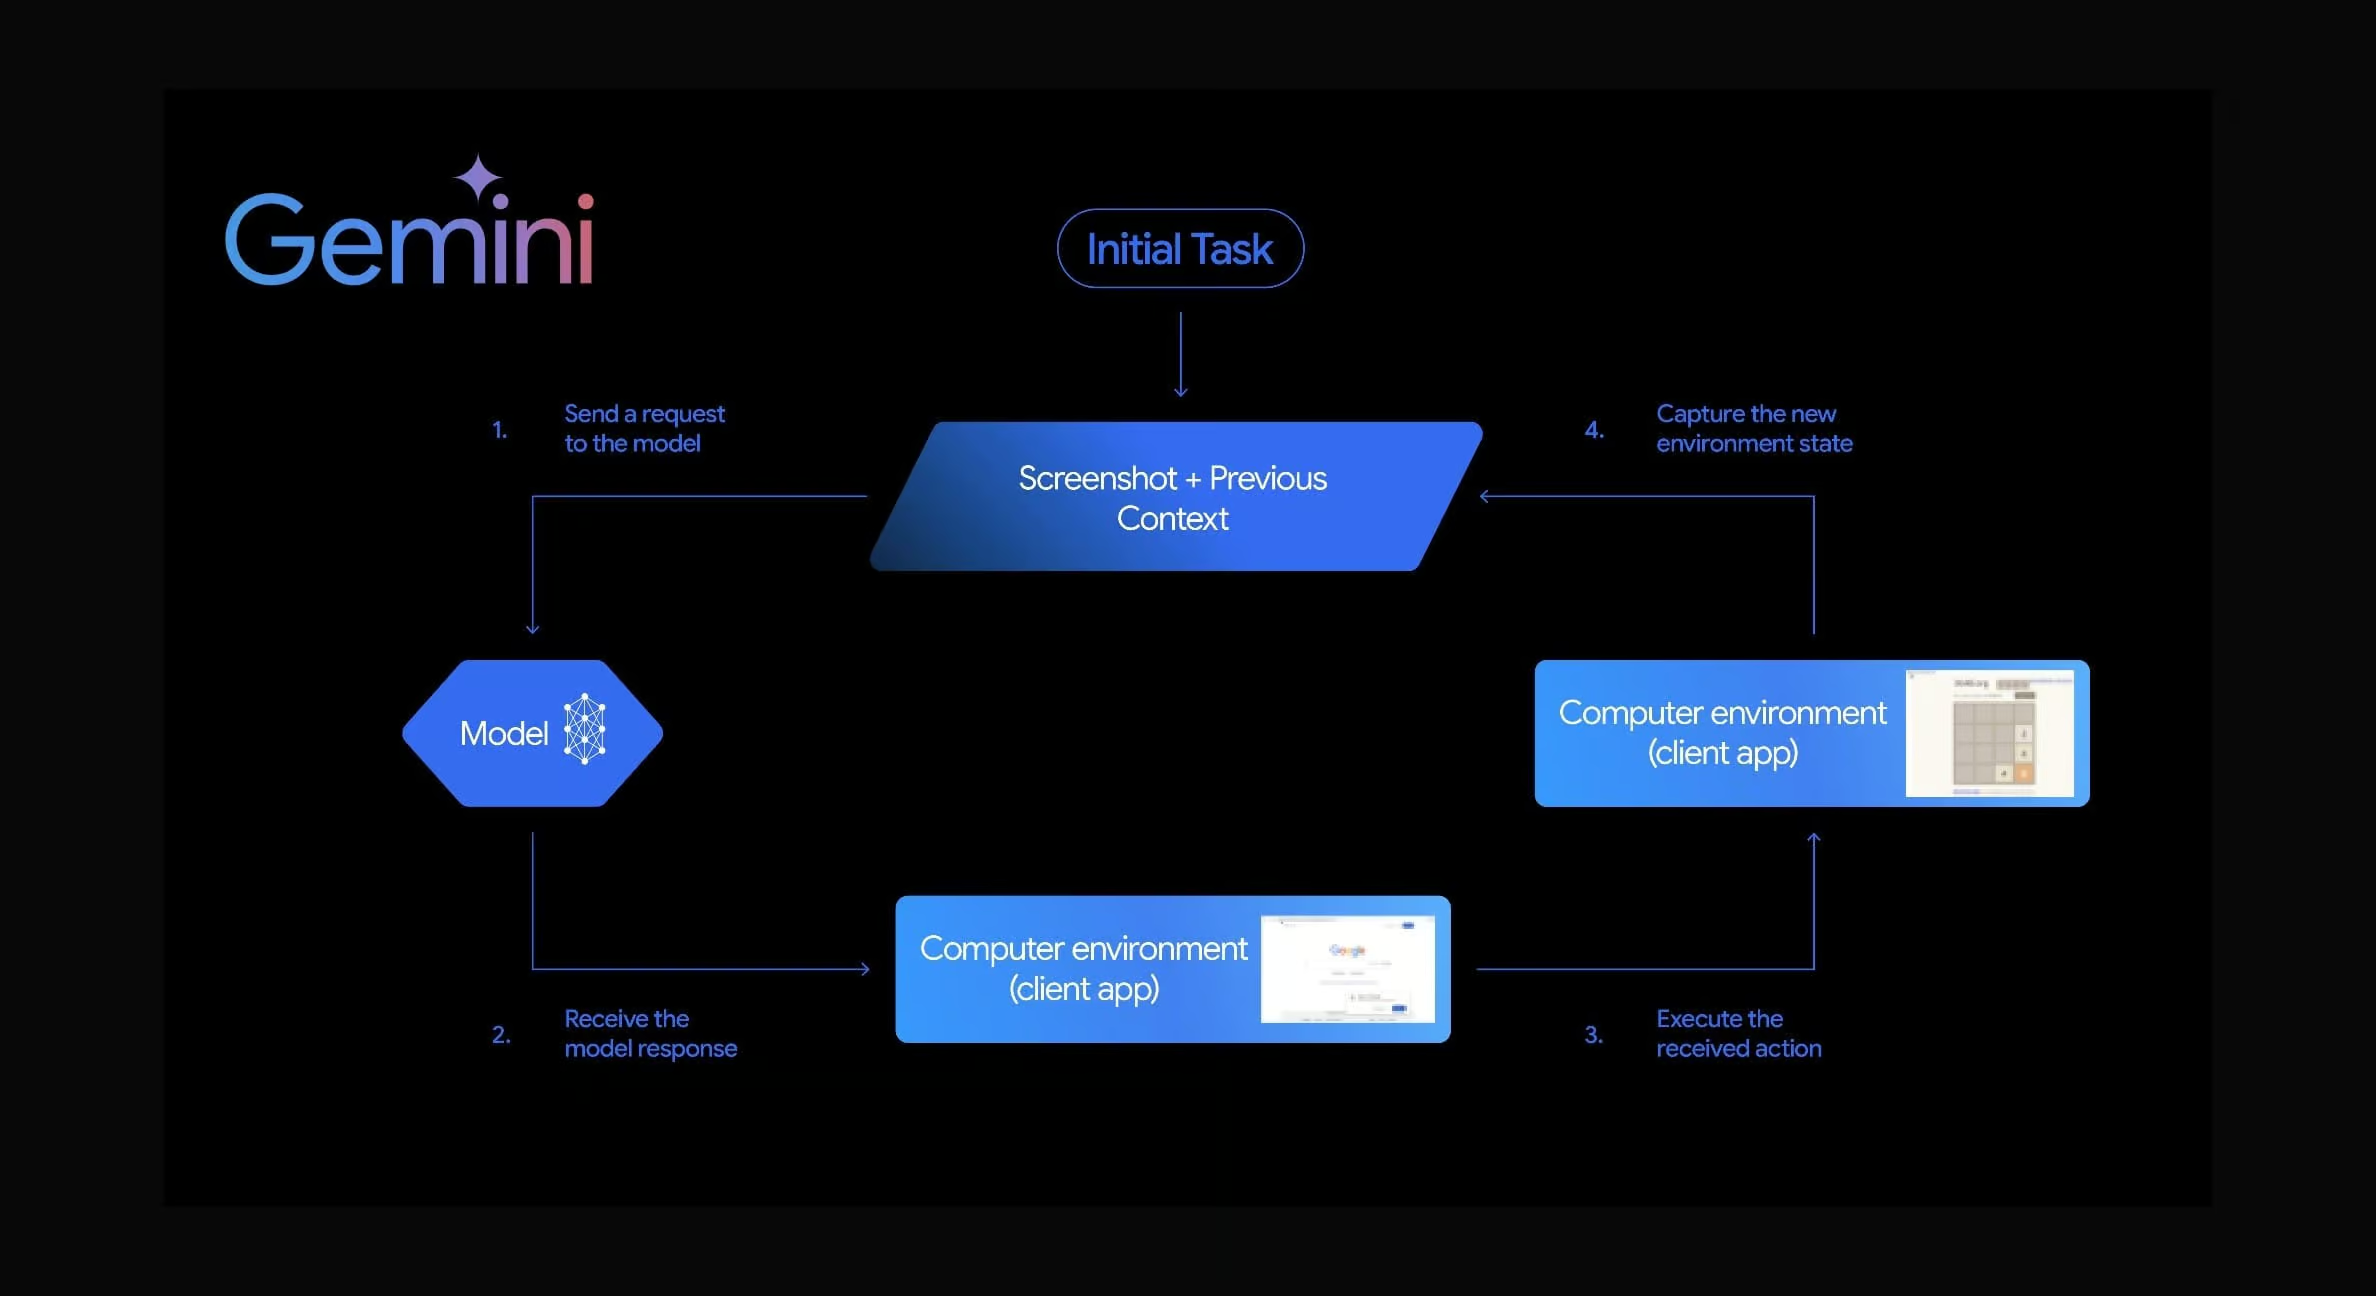
    An agent built on this feature runs a continuous loop. Developer code sends a screenshot of the current page and the user’s request to the model. The model replies with a function call describing the next action, often including coordinates and a target element. Developer code performs that action in a real browser, takes a fresh screenshot, and feeds it back. The cycle repeats until the task finishes or a stopping condition triggers.

    Each turn produces a structured response, which means the agent’s decisions can be logged, replayed, and scored during audits. For SEO teams reviewing their own pages, that loop is also the lens for asking what an agent might do badly on your site.

    Model requirements and project setup

    Computer use runs on one specific Gemini model rather than the entire family. To use it, the developer’s project needs access to that model, a recent release of the Google GenAI SDK, the right environment variables for authentication, and the feature flag turned on. A simple request-response loop is enough for testing; production deployments tend to add a managed orchestration layer on top.

    Prompts and context that shape agent behavior

    The system prompt defines what the agent believes it is allowed to do, what UI actions are available, and what constraints apply. Strong prompts name the environment clearly, set confirmation requirements for sensitive actions, cap navigation depth, and describe how to recover from errors.

    Sending extra context with each screenshot, such as the current URL, the last few actions, or a short progress note, tends to make the agent more reliable. Confirmation prompts before destructive actions like deleting a record or submitting a payment should live in both the prompt and the application code.

    What an audit checklist for agent-ready pages should cover

    Stable selectors and visible targets

    Agents sometimes get coordinates from the model rather than CSS selectors, but they still rely on the page exposing predictable buttons, inputs, and links. Audit your key templates for unique, stable selectors on every interactive element, and confirm that the elements you care about remain visible without JavaScript that may be blocked.

    Sensitive actions behind explicit approval

    Any action that submits data, changes an account, or triggers an irreversible effect should sit behind an additional confirmation step in your code, not just in the prompt. Treat the prompt as advisory and the application code as the authority.

    Allowed domains and URL hygiene

    Many deployments restrict the agent to a list of allowed domains. Make sure your important flows live on predictable hostnames, and avoid scattering a single journey across many subdomains if you want the agent to follow it.

    Login walls, captchas, and popups

    Agents routinely stall on login screens, captchas, and unexpected modals. Test each critical path for those interruptions and design explicit recovery paths, including a documented human handoff when the agent is stuck.

    Screenshot hygiene

    Screenshots can capture personal data, session tokens, or one-time codes that are visible on screen. Audit pages that show such data and either suppress the visible values, mask them in the UI, or require re-authentication before the agent reaches them.

    Safety considerations operators should not skip

    Browser automation has always carried risk, and this feature inherits all of it. Page structures change without notice, screenshots may carry sensitive data, and irreversible actions are reachable from the UI. Reasonable mitigations include validating that a planned click targets an expected element, scrubbing screenshots before they are stored, restricting the agent to approved domains, and requiring user approval for any high-risk action.

    Reliability also depends on how the agent handles popups, login screens, captchas, and surprise redirects. Recovery flows for those cases belong in the application layer, not just in the prompt.

    Where computer use is the right tool

    Computer use fits workflows where the only available surface is a browser, where no API exists, or where legacy systems cannot be integrated through structured data. Examples include filling forms across multiple web portals, pulling data from internal dashboards, and helping users through repetitive navigation steps.

    For tasks with a clean API or a well-defined schema, function calling and structured output remain simpler and more predictable. Computer use earns its keep when the visual interface is the only practical path, and when the site owner has done the work to make that interface agent-friendly.

    FAQ

    What is the Gemini API computer use feature in plain terms?

    It is a Gemini API capability that lets developers build agents which read rendered pages as screenshots and perform browser actions like clicking, typing, and scrolling. It is delivered through a specialized endpoint and runs alongside existing function calling and structured output tools.

    Which Gemini model powers the computer use capability?

    Computer use is offered on a specific Gemini model rather than the full family. Developers must enable the feature in their project, install a recent version of the Google GenAI SDK, and confirm workspace access to that model before sending requests.

    What should I check on my site before a computer use agent visits it?

    Verify that interactive elements expose stable selectors and coordinate targets, that sensitive screens sit behind confirmation steps, that allowed domain lists include your pages, and that no irreversible actions are reachable from the rendered UI without an extra approval step.

    Related coverage

  • 100% Tariff Threat Targets Countries With Digital Services Taxes: What Site Owners Should Audit Now

    100% Tariff Threat Targets Countries With Digital Services Taxes: What Site Owners Should Audit Now

    A 100% tariff on every product arriving in the United States from any country that taxes American tech companies would represent one of the sharpest economic countermeasures tied to digital policy in modern trade history. President Trump posted the warning on Truth Social on Friday, declaring that the levy would override every existing trade deal and apply to any nation that passes or enforces a digital services tax. For site owners who run technical SEO audits, the story matters less as a political headline and more as a set of concrete variables that can move ad spend, hosting costs, and cross-border checkout flows.

    Why a digital tax fight is an SEO and infrastructure problem

    Six European and transatlantic economies already collect revenue-based levies on digital platforms. France has run a 3% digital services tax since 2019 on companies earning more than €25 million in French revenue and €750 million globally, and French lawmakers have proposed raising the rate to 6%. Italy and Spain each apply 3% on selected digital revenues. The United Kingdom levies 2% on large search engines, social media platforms, and online marketplaces. Austria charges 5% on online advertising income, and Turkey taxes digital services at 7.5%. Most of these frameworks were built to capture revenue from U.S.-headquartered platforms such as Google, Apple, Microsoft, Meta, and Amazon, which dominate search, social advertising, e-commerce infrastructure, and cloud computing.

    When a country raises the rate or widens the scope, the operator typically absorbs part of the cost and passes the rest to advertisers, sellers, and subscribers. That is the channel through which a French rate hike reaches a U.S. small business running Google Ads or listing products on Amazon Marketplace. The new tariff threat raises the stakes by turning a low single-digit levy into a potential 100% surcharge on physical exports to the U.S., which can ripple into the hardware, networking gear, and equipment that quietly powers a website’s stack.

    What the announcement actually says

    Trump’s post did not leave room for gradual enforcement. The text stated: “Any Country that imposes such a Tax will immediately be met with a 100% TARIFF on any and all Goods sent to the United States of America. This TARIFF will supersede Trade Deals made with the Country, whether implemented, signed, or not.” Because the language refers to any country that “imposes such a Tax” without distinguishing between new and existing laws, it is not yet clear whether France, Italy, Spain, the UK, Austria, and Turkey, which already collect these levies, would be hit immediately or only if they tighten their rules. The White House has not clarified the scope.

    The threat also arrived one day after the EU Council approved tariff commitments under a joint U.S. trade statement, meaning the 100% figure would override the rates just negotiated. A 100% tariff on French wine, Italian machinery, Spanish agricultural products, British automobiles, Austrian goods, or Turkish exports would be large enough to redirect trade flows within weeks.

    What to audit on your own site right now

    An SEO audit is normally about crawlability, structured data, and Core Web Vitals, but trade turbulence changes which questions deserve a line item. Five checks belong on the next crawl report.

    Ad spend exposure by platform and country of sale

    Pull the last 90 days of Google Ads, Meta Ads, and any other paid search or social campaigns and tag each campaign by target country. If a meaningful share of impressions or conversions routes through France, Italy, Spain, the UK, Austria, or Turkey, those campaigns are the first place a tax-driven price increase would surface. Watch for rising cost per click and cost per acquisition even before any official rate change, since platforms sometimes adjust auction floors in advance of regulatory news.

    Hosting, CDN, and SaaS billing geography

    Cloud bills from hyperscale providers, CDNs, email platforms, and analytics tools often include line items tied to the jurisdiction where data is processed. If your providers pass digital services taxes through, expect new surcharge lines on invoices from European regions. Audit every vendor contract for clauses about tax pass-through, currency conversion, and unilateral price changes so you can model the worst case before it shows up on the next statement.

    Cross-border checkout and shipping logic

    Run a crawl of your product or landing pages that target European customers and confirm that shipping calculators, duty estimates, and tax-inclusive pricing still match the current rate environment. A 100% tariff would not only raise the landed cost of imported goods but could also break assumptions in your structured data, such as schema.org/Offer price fields, if your CMS pulls live rates. Document the current values so a future comparison is clean.

    Backlink and partnership exposure

    Tariff news tends to redirect editorial attention toward the affected countries. Audit referring domains from French, Italian, Spanish, British, Austrian, and Turkish publishers and partners. A sudden drop in coverage from those markets, whether because partners pause campaigns or media outlets pivot to other stories, can quietly reduce topical relevance signals that search engines weigh.

    Structured data and hreflang for European markets

    Make sure hreflang clusters, currency markup, and availability attributes still describe the markets you actually serve. If you temporarily pull out of a market, leaving stale hreflang tags pointing to live URLs can produce soft 404 patterns and confuse crawlers about which version of a page to index.

    How regulators and governments are responding

    French President Emmanuel Macron has framed the dispute as a question of “digital sovereignty” and has moved government services away from Microsoft software. France’s domestic intelligence agency, DGSI, recently announced plans to replace AI software from U.S. defense contractor Palantir with a domestic alternative, a concrete signal that tech decoupling is moving from rhetoric to procurement decisions. The European Commission’s Digital Markets Act and Digital Services Act add competition, transparency, and content-moderation obligations that U.S. officials have criticized as aimed at American firms.

    The U.S. Trade Representative has already threatened retaliatory tariffs against Britain, Austria, Spain, and other European countries over their digital tax regimes. If a 100% tariff takes effect, expect reciprocal tariffs from the EU and potentially from the UK, which would pull global digital commerce into a broader trade conflict.

    The concrete numbers behind the headline

    • 100% proposed tariff on all goods from any country that imposes a digital services tax on American firms.
    • 3% French digital levy in force since 2019, with proposals to raise it to 6%, applied above €25 million in French revenue and €750 million in worldwide revenue.
    • 3% taxes in Italy and Spain on selected digital revenues.
    • 2% UK tax on large search engines, social media platforms, and online marketplaces.
    • 5% Austrian tax on online advertising revenue.
    • 7.5% Turkish digital services tax.
    • Existing retaliatory tariff threats from the U.S. Trade Representative against the UK, Austria, Spain, and other European countries.

    What changes next, and how to stay ahead of it

    Watch for two specific triggers. The first is any French legislative action on the proposed 6% rate, since France is the largest European digital advertising market by revenue. The second is any U.S. Trade Representative statement clarifying whether the 100% tariff applies to countries that already enforce digital services taxes, since that answer determines whether existing campaigns and contracts need immediate repricing. Until the scope is defined, treat every percentage point of European digital tax as a potential line item on your next cloud or ad invoice and document the baseline today.

    FAQ

    What is a digital services tax?

    A digital services tax is a levy a country collects on revenue earned by large digital platforms from activities such as online advertising, marketplace transactions, and user data sales. It typically targets companies with significant digital activity in the country but limited physical presence. France, for example, applies a 3% rate on companies earning more than €25 million in French revenue and €750 million globally.

    Which countries already have digital services taxes?

    France has applied a 3% rate since 2019 and has proposed doubling it to 6%. Italy and Spain each levy 3% on certain digital revenues. The UK charges 2% on large search engines, social media platforms, and online marketplaces. Austria taxes online advertising at 5%, and Turkey taxes digital services at 7.5%.

    Would the 100% tariff apply only to new digital taxes or to existing ones too?

    Trump’s statement covered “any Country that imposes such a Tax” without specifying whether existing levies count. The White House has not clarified whether France, Italy, Spain, the UK, Austria, or Turkey, which already enforce digital taxes, would be subject to the 100% tariff immediately or only if they change their rules.

    Related coverage

  • What a Virginia Generator Standoff Means for Auditing Sites Near Data Center Buildouts

    What a Virginia Generator Standoff Means for Auditing Sites Near Data Center Buildouts

    Residents living next to the Vantage Data Centers facility in Sterling, Virginia have spent more than a year under a high-pitched whine from the site’s backup generators, which were first described to the neighborhood as a temporary emergency test. The generators are now running around the clock as the facility’s primary power source, prompting neighbors to install plexiglass over windows, track decibel readings on handheld meters, and consult lawyers. The standoff has turned a quiet Loudoun County subdivision into a flashpoint over where AI’s physical footprint is allowed to land, and it carries direct lessons for anyone auditing a site inside the country’s densest data center market.

    Why Sterling Is the Audit Case That Matters Now

    Virginia hosts 287 operational data centers and has 398 more in the pipeline, according to Pew Research, the largest concentration in the United States. Loudoun County, sometimes called Data Center Alley, collects almost half of its property tax receipts from these facilities, and the sector consumed roughly 26 percent of Virginia’s total electricity in 2023, a share large enough to bend statewide rate cases. The Vantage Sterling site pushes that footprint to an extreme: it runs entirely on its own on-site power plant, with no grid connection. That model can shield ratepayers from utility bill increases, a policy the Trump administration has encouraged, but it also shifts every operational side effect, from emissions to noise, into a neighbor’s backyard.

    What Actually Changed on the Ground

    Homeowners were told the generators would be tested periodically to confirm they would work during a grid outage. Over months, the testing never stopped, and the sound persisted 24 hours a day. Resident Hari Doue told reporters that the original framing of emergency testing no longer matches reality. Greg Pirio, another neighbor, described the effect plainly and has reached out to attorneys. Some households have pressed mattresses against windows in an attempt to sleep. The complaints now cluster around three measurable harms: sleep disruption, elevated stress, and falling property values.

    The Local Noise Standard and Where It Breaks

    Loudoun County caps noise at 55 decibels in residential and rural zones and 60 decibels in mixed-use residential zones, with carve-outs for generator operation during emergencies, utility requests, or testing. Vantage officials say they monitor levels at the site and do not believe the facility exceeds those thresholds. Residents counter that an occasional test and a permanent power plant are not the same thing. The dispute has exposed a gap in how local ordinances treat backup equipment that quietly becomes primary equipment.

    What Site Owners Near Buildouts Should Be Checking

    If your business, hosting provider, or client sits inside or adjacent to a dense data center cluster, the Sterling case suggests several items that belong on a technical audit checklist. First, confirm whether your facility draws from the grid or runs on co-located or behind-the-meter generation, since on-site power plants change uptime math and noise exposure simultaneously. Second, pull local zoning and conditional-use permits for the parcel and read the generator testing schedule, because what is permitted as intermittent testing rarely anticipates continuous operation. Third, capture and archive decibel logs and community complaint records from county meeting minutes; these show up later in property tax assessments, insurance underwriting, and litigation discovery. Fourth, track whether your county or independent city has updated its noise ordinance to close the testing-versus-operation loophole, since that gap is now the focus of organized resident action in Loudoun. Fifth, map the nearest residential parcels within a 10 to 15 mile radius, the buffer Doue urged planners to enforce, and weigh that distance against latency, fiber, and power redundancy needs before signing a multi-year colocation contract.

    Why the Federal Layer Just Entered the Picture

    On June 18, 2026, the Federal Energy Regulatory Commission issued show-cause orders requiring major grid operators to justify or update their rules for connecting large energy users such as data centers. The action moves the conversation from local zoning hearings into federal transmission planning, and it puts on-site generation under sharper review. If dedicated off-grid power becomes the default for new AI campuses, the operational question shifts from whether a backup ran during an outage to how loud a site is when the generators never shut off. That reframing will ripple through permitting timelines, environmental reviews, and rate cases for every utility serving a data center cluster.

    How the AI Capacity Race Connects to Local Friction

    The Sterling fight is inseparable from the broader push to expand GPU capacity. Demand for new clusters has accelerated land-use conflicts alongside product rollouts, and federal digital trade policy, including tariff threats aimed at countries with digital services taxes, is now fused to the same infrastructure buildout. When a household pushes a mattress against a window to muffle a generator, that is a local price tag on the same capacity race driving hyperscale construction.

    What to Watch in the Next Quarter

    Three signals will tell you whether Sterling stays a local story or becomes a template. Look for Loudoun County or the Virginia General Assembly to amend the noise ordinance to cover continuous generator operation, not just testing windows. Watch for FERC proceedings to produce revised interconnection rules that account for hyperscale loads and behind-the-meter generation. And track whether other Vantage campuses or rival operators in Data Center Alley disclose on-site generation as a permanent design choice, because each new site that goes off-grid adds another potential Sterling.

    FAQ

    What is producing the constant noise near the Vantage Sterling data center?

    The Vantage Data Centers facility in Sterling, Virginia operates entirely on its own on-site power plant with no grid connection. Generators originally framed as emergency backup equipment are now running continuously as the primary power source, producing a persistent high-pitched whining or ringing sound that neighbors have logged on personal decibel meters.

    What are Loudoun County’s noise limits, and is Vantage exceeding them?

    Loudoun County sets 55 decibels in residential and rural zones and 60 decibels in mixed-use residential zones, with exceptions for emergency generator operation, utility requests, or testing. Vantage officials say on-site monitoring shows the facility stays inside those thresholds, while residents argue the continuous-operation reality goes well beyond what the testing exemption was written to cover.

    What did FERC order on June 18, 2026 about data centers?

    On June 18, 2026, the Federal Energy Regulatory Commission issued show-cause orders directing major grid operators to justify or update their rules for connecting large energy users such as data centers. The move brings federal scrutiny to how hyperscale loads and behind-the-meter generation are integrated into the transmission system.

    Related coverage

  • Eastern Interconnection Emergency Reserves Projected to Run Out by 2027

    Eastern Interconnection Emergency Reserves Projected to Run Out by 2027

    The Eastern Interconnection, the largest synchronized power grid in North America, is projected to run out of its deepest tier of emergency peak power reserves by June 2027. Once that final buffer is gone, grid operators will have no choice but to start shedding load through controlled rotating outages during the worst summer demand peaks. The finding comes from recent energy reliability analysis tracking how the reserve margin is shrinking year after year as coal and nuclear plants retire faster than new dispatchable generation comes online, while demand keeps climbing from data centers and electrification.

    Why the Reserve Margin Matters for Site Owners

    The Eastern Interconnection stretches from the Great Plains to the Atlantic seaboard, carrying power to factories, hospitals, data centers, and millions of homes. Operators maintain several reserve tiers to keep the system stable. Emergency peak reserves sit at the bottom of that stack and are used only when extreme heat, a major plant trip, or another stressor threatens to push demand past supply. Once those reserves are gone, the grid is one unplanned outage away from cascading failures that cross state lines.

    For anyone running an online business, the implication is direct. If a rolling blackout hits a region where your servers, payment processors, or SaaS vendors operate, customer-facing services stop responding and revenue stops flowing. The June 2027 forecast turns a distant infrastructure concern into a planning problem that belongs on a technical SEO and operations checklist today.

    How the Numbers Got This Tight

    The headline projection is straightforward: June 2027 is the expected month when emergency peak reserves reach zero under a typical summer demand curve. Three pressures are doing the work behind that date.

    • Retiring baseload. Older coal and nuclear units are leaving the system faster than replacements are being built.
    • Slow additions of dispatchable generation. Gas, hydro, and other plants that operators can call on demand are coming online at a pace that lags consumption growth.
    • Climbing load from data centers and electrification. AI training facilities, crypto sites, EV charging, and building electrification are pushing peak demand higher every summer.

    Each summer eats into the buffer a little more. By June 2027, the arithmetic no longer leaves headroom for an additional surprise.

    What Grid Operators Will Likely Do Next

    Utilities and federal regulators are expected to push faster permitting for fast-ramp generation and grid-scale battery storage, expand demand response programs that pay large customers to curtail usage during tight hours, and revive transmission projects that can import power from regions with surplus capacity. Most of those projects take years to clear planning and construction, so the near-term lever is interruptible-rate tariffs that compensate commercial and industrial customers for agreeing to drop load when called.

    The conflict is already playing out locally. In Sterling, Virginia, neighbors filed complaints over the noise and emissions from backup generators at a Vantage Data Center facility, a sign that on-site power built to defend against grid fragility is itself becoming a quality-of-life issue. Expect more disputes of this kind as digital infrastructure scales faster than the grid underneath it.

    What to Audit on Your Own Stack Before Summer 2027

    Treat the reserve projection the way you would treat a Core Web Vitals regression: measure, prioritize, and fix the worst exposure first. A useful audit walks four layers.

    1. Map Your Dependency Geography

    Identify every provider in your stack that runs inside the Eastern Interconnection: your hosting region, your CDN POPs that serve U.S. traffic, your payment processor’s primary data centers, your DNS anycast nodes, and the home offices of remote team members. Anything in that footprint is a candidate for a rotating outage. For each, note whether the provider publishes a multi-region failover option and whether your contract gives you a service level credit when uptime targets are missed because of regional power events.

    2. Review Your Uptime and Incident Response Assumptions

    Most status pages assume a software or network failure. A rolling blackout looks like a simultaneous, multi-hour outage that affects your office, your staff’s homes, and your provider’s data center at once. Update your incident runbook to include a power-loss scenario: who has authority to declare an outage, what gets communicated to customers, and which non-essential workloads get shut down first to extend UPS runtime.

    3. Check the Physical Layer You Control

    If you operate your own server room or a small on-prem cluster, a properly sized uninterruptible power supply bridges the gap between a grid drop and a generator spinning up. Confirm the UPS has been load-tested in the last 12 months, that the transfer switch is set to generator mode, and that fuel reserves cover at least 24 hours at expected load. Replace any battery that shows swelling or that has passed its service date.

    4. Pressure-Test Cloud and Colocation Contracts

    For AI inference or training jobs that cannot be paused mid-run, ask your cloud provider for documentation of their data center backup power architecture, the duration their fuel reserves are designed to cover, and whether multi-region deployment is available for your workload tier. If the answers are vague, treat that as a finding in your next vendor review and price out a colocation facility with dedicated power feeds as a secondary site.

    How This Connects to Broader Site Reliability Work

    Site reliability conversations usually focus on caching, rendering, and dependency health. The June 2027 reserve projection adds a fourth axis: the physical grid that feeds every rack your service depends on. Crawl budgets, schema coverage, and link audits will not help if a rotating outage takes your primary region offline during a product launch or a search-driven traffic spike.

    Operators that build a layered power resilience plan now, combining UPS, on-site generation, multi-region replication, and a tested communication tree, will be the ones still serving traffic when the reserve margin finally hits zero. The Eastern Interconnection has been a background utility for decades; starting in 2027, it is a variable you have to plan around.

    FAQ

    What is the Eastern Interconnection?

    The Eastern Interconnection is the largest synchronized power grid in North America, covering most of the United States east of the Rocky Mountains and extending from the Great Plains to the Atlantic coast. It connects thousands of generating plants through high-voltage transmission lines, with operators coordinating continuously to balance supply and demand across the region.

    What are emergency peak reserves?

    Emergency peak reserves are the deepest tier of backup capacity that grid operators can deploy. They sit below spinning reserves and contingency reserves and are activated only after every other measure has been used during an extreme demand event. If those reserves are exhausted, operators must begin controlled rolling blackouts to prevent a wider system collapse.

    How should site owners prepare for possible rotating blackouts?

    Audit which parts of your stack live inside the Eastern Interconnection, confirm UPS and generator readiness for any on-prem equipment, review cloud and colocation contracts for backup power guarantees and multi-region failover, and update your incident response runbook to include a multi-hour power-loss scenario that affects both staff and providers at the same time.

  • What Intercept’s $500M Push Means for Auditing Pages Built Around AI Health Bets

    What Intercept’s $500M Push Means for Auditing Pages Built Around AI Health Bets

    Intercept, a $500 million philanthropic initiative, convened roughly 40 scientists, pharma R&D leaders, biotech venture capitalists, and regulatory experts at a Stripe symposium in August. The group concluded that respiratory infections are a tractable engineering problem hidden behind decades of underfunding, and that two product categories, broad-spectrum preventatives and air-cleaning technologies, could sharply reduce the burden of colds, flu, and other respiratory viruses.

    For technical SEO practitioners covering the AI-health crossover, that framing has direct audit implications: any page built around this story inherits specific factual claims, named statistics, and product categories that demand careful markup, source attribution, and freshness signals. Below is a practical rundown of the facts, what they actually say, and where pages covering this beat tend to slip.

    What Intercept is funding, and why the framing matters for pages about it

    Intercept is steering its $500 million toward two complementary defenses. The first is broad-spectrum preventatives, or BSPs, drugs and vaccines that protect against rhinoviruses, influenza, coronaviruses, and other respiratory viruses at once. The second is air-cleaning technologies, or ACTs, such as advanced air filtration and far-UVC antimicrobial light aimed at high-density spaces like offices, schools, and public transit.

    Pages that summarize this initiative often collapse both categories into a single sentence. That is a problem for E-E-A-T review, because the two have very different evidence profiles. BSPs include adaptive immunity approaches (CD8 T cells stationed at the site of infection), direct-acting antivirals (siRNA and small molecules hitting conserved proteins like RNA polymerase), innate immunity modulators (engineered interferons, cGAS and RIG-I agonists), host-directed antivirals, and physical barrier formulations like nasal sprays and viral-binding lectins. ACTs are mechanical and photophysical, not pharmacological. If your page flattens that distinction, Google’s quality raters may flag it as surface-level coverage, especially under YMYL scrutiny.

    The numbers every page on this topic should handle correctly

    Several statistics in the Intercept announcement are likely to be quoted widely. Each one has a specific scope and denominator that pages tend to drop:

    • 15 to 25 days a year: Time the average healthy adult spends sick with a respiratory infection, about 5% of life.
    • 12.8 billion infections in 2021: Global respiratory infection count, the vast majority viral.
    • 65 million+ annually: Cases that progress to serious lower respiratory disease.
    • ~7% of U.S. deaths from major causes: Share tied to respiratory infections.
    • $600 billion, or ~0.6% of global GDP: Annual productivity drag from routine respiratory illness in non-pandemic years.
    • 67% population protection: Threshold needed to approach elimination of a virus with an R0 of 3.0.
    • ~40: Scientists, pharma R&D leaders, biotech VCs, and regulators convened at the Stripe symposium.
    • $500 million: Size of Intercept’s philanthropic commitment.

    When auditing a page, check that each of these retains its qualifier. The $600 billion figure is explicitly framed as a non-pandemic-year estimate, and the 9.8x asthma risk applies to children infected with human rhinovirus between birth and age three in a high-risk cohort, not to all children. Stripping the cohort qualifier turns an interesting finding into a misleading claim, and misleading claims are the exact thing YMYL reviewers look for.

    Downstream health links that pages often misattribute

    Intercept’s framing leans heavily on long-tail comorbidities, and these are exactly the statistics that get copied from one post to the next without attribution. The strong claims to watch for:

    • A heart attack is 6.1x more likely in the seven days after an influenza infection.
    • Severe influenza is associated with a 4.5 to 5x increase in dementia risk.
    • Severe influenza and pneumonia together are linked to a 2.6 to 4.1x increase in Alzheimer’s risk.
    • Maternal influenza during pregnancy has been associated with a 2.2 to 3x potential increase in schizophrenia risk for the infant.

    Two audit checks fall out of this list. First, association is not causation: every page citing these multipliers should preserve words like “associated with” or “linked to.” Second, each figure traces back to specific peer-reviewed studies, and those citations are where the real E-E-A-T signal lives. A page that names Intercept but cannot link to the underlying paper for, say, the 6.1x heart attack figure is thinner than a page that does.

    Why the R0 and uptake math matters for technical audits

    Intercept’s headline argument rests on a quantitative claim: even a near-perfect preventative at 60% uptake cannot eliminate a virus with a basic reproduction number of 3.0 on its own. Roughly 67% population protection is needed to push the effective reproduction number below 1. ACTs close the gap by reducing virions in shared indoor air.

    For pages that quote this logic, the audit hook is consistency. If a post cites 60% uptake and 67% needed, those numbers should appear in the same paragraph and refer to the same baseline. If they appear in different sections without that linkage, the page reads like stitched-together coverage rather than synthesized reporting, which weakens both topical authority and reader trust.

    How to structure a page that ranks for this story

    Based on the source material, a page that wins on this topic tends to do three things right:

    1. Distinguishes BSPs from ACTs early and explains why both are needed, rather than treating one as a footnote.
    2. Lists the five BSP approaches (adaptive immunity, direct-acting antivirals, innate immunity modulators, host-directed antivirals, physical barrier formulations) with at least one named example each, such as siRNA, CD8 T cells, engineered interferons, lectins, or mucin domains.
    3. Keeps the pandemic-era context visible. Before 2020, broad-spectrum programs were sparse; the pandemic briefly flooded the field with capital and produced candidates like pan-sarbecovirus vaccine prototypes, host-targeted small molecules, engineered interferons, and SARS-CoV-2 siRNAs, many of which stalled when strain-specific COVID vaccines succeeded.

    Those three moves are also where structured data can help. An Article schema with a clear about field pointing at “broad-spectrum preventatives” and “air-cleaning technologies,” plus a citedBy or mentions property for each underlying study, gives parsers a way to connect the page to the science rather than to the announcement alone.

    Freshness and update cadence

    Intercept’s last-updated date is June 25, 2026, and the symposium itself took place in August. Because the initiative is mid-pipeline, with funding decisions still unfolding, any page covering this story should carry a visible dateModified field and a recent datePublished. A page that quotes a 2021 infection tally as if it were a 2026 figure will read stale, and a fresh date stamp alone is not enough: the body must also reflect the latest milestone or the page drops out of fast-moving SERPs.

    FAQ

    What is Intercept funding with its $500 million?

    Intercept is directing $500 million toward broad-spectrum preventatives (BSPs) that defend against multiple respiratory virus families at once and air-cleaning technologies (ACTs) like advanced filtration and far-UVC light. The goal is to sharply reduce and eventually eliminate colds, flu, and similar illnesses.

    Why do broad-spectrum preventatives need air-cleaning tech to reach elimination?

    Even a near-perfect preventative cannot eliminate a virus with an R0 of 3.0 if uptake sits at 60%. Roughly 67% population protection is needed to push the effective reproduction number below 1. Air-cleaning technologies reduce virions in shared indoor air and close that gap.

    Which statistics on Intercept pages are most often quoted wrong?

    The most commonly misquoted figures are the 9.8x asthma risk, which applies only to a high-risk cohort of children infected with human rhinovirus between birth and age three, and the $600 billion productivity drag, which is explicitly a non-pandemic-year estimate. Pages that drop those qualifiers turn specific findings into sweeping claims.

    Related coverage

  • Mini Shai-Hulud Supply-Chain Attack: What Site Owners and Dev Teams Need to Audit Now

    Mini Shai-Hulud Supply-Chain Attack: What Site Owners and Dev Teams Need to Audit Now

    Between May 11 and May 12, 2026, a coordinated software supply-chain compromise infected official Mistral AI SDKs on both npm and PyPI, plus three core TanStack JavaScript libraries. The injected code harvested developer secrets, opened a backdoor for credential theft, and shipped a destructive payload that could wipe Linux hosts. Anyone shipping production code through automated pipelines needs to treat this as an active incident on their own infrastructure.

    The campaign used trusted, widely downloaded packages as the entry point. That makes reputation-based allowlists and casual lockfile reviews useless as a defense. Below is a walk-through of how the attack worked, what to grep for in your own projects, and the structural changes worth making before the next wave hits.

    How a Trusted Package Became the Entry Point

    Two parallel waves struck during a 24-hour window. The first wave, beginning around 19:20 UTC on May 11, republish ed several TanStack packages with injected code: @tanstack/react-router, @tanstack/history, and @tanstack/router-core. These libraries sit underneath thousands of React routing implementations, and each is downloaded tens of millions of times per week.

    Within hours, the same operator compromised three Mistral AI npm SDKs: @mistralai/mistralai, @mistralai/mistralai-azure, and @mistralai/mistralai-gcp. On the Python side, version 2.4.6 of the mistralai package on PyPI was trojanized. The attack vector was identical in each case: legitimate maintainer or publisher credentials were used to push a new version containing hostile code, so the registry itself treated the upload as authentic.

    What the Payload Actually Did on Linux Hosts

    The mistralai PyPI trojan embedded its code directly in mistralai/client/__init__.py, a module that runs the moment any downstream script imports the package. On Linux systems, the injected code issued a curl request to the command-and-control host at 83.142.209.194 and saved the response to /tmp/transformers.pyz. The filename was chosen to mimic Hugging Face’s Transformers library, so the dropped file blends into the typical noise of an AI development workstation.

    Once executed, the second-stage payload detached from the parent Python process and ran independently in the background. It scanned the host for high-value secrets: GitHub personal access tokens, npm publishing tokens, cloud provider API keys, SSH keys, and CI/CD environment variables. All visible errors were suppressed, which is why no install script ever raised a warning.

    Two details make this payload worse than a typical stealer. First, it contains logic that checks the system locale and exits without doing anything on Russian-language Linux installs, a pattern consistent with financially motivated actors filtering out their own geography. Second, a destructive branch can issue rm -rf / under certain geographic conditions, irreversibly wiping any host it reaches.

    Indicators of Compromise Worth Hunting For

    Start with the artifacts the analysts have already named. The dropped payload lives at /tmp/transformers.pyz on Linux. Watch for outbound traffic to 83.142.209.194 from build runners, developer laptops, and any container that ever installed one of the affected packages. Microsoft Threat Intelligence has also flagged two additional artifacts that may appear on hosts that ran the second stage: pgmonitor.py and pgsql-monitor.service. Treat both as high-confidence signals of compromise and rotate everything those hosts touched.

    Beyond those named indicators, run a focused review of any process that detached from a Python or Node.js install script and is still running in the background. Cross-reference process start times against the exact install windows for the compromised package versions.

    The Audit Checklist for Your Own Dependency Tree

    The compromised packages are not obscure transitive dependencies. They are flagship SDKs and routing libraries that pass every reputation check a typical allowlist runs. That is exactly why a manual review is the only reliable defense right now. Walk through these steps in order.

    • Grep every package.json, pnpm-lock.yaml, yarn.lock, and package-lock.json for the six exact package names: @tanstack/react-router, @tanstack/history, @tanstack/router-core, @mistralai/mistralai, @mistralai/mistralai-azure, @mistralai/mistralai-gcp.
    • Grep every requirements.txt, poetry.lock, Pipfile.lock, and pyproject.toml for mistralai at version 2.4.6 and any newer version published after May 11, 2026, until the registry confirms the malicious release has been yanked.
    • Run npm audit and pip-audit across the full dependency tree, including dev dependencies. Audit tools may not flag these specific versions yet, so treat the output as a secondary check.
    • Search CI and build logs for any outbound connection to 83.142.209.194 between May 11 and the present.
    • Check production servers and developer workstations for /tmp/transformers.pyz, pgmonitor.py, and pgsql-monitor.service.

    If you find any of the above on a host that runs builds or holds secrets, treat the host as fully compromised. Reimage, do not clean.

    What to Rotate and Where to Revoke

    The credential sweep is the single highest-leverage action. The payload targeted secrets that grant publish rights and cloud access, not just application credentials. Rotate in this priority order.

    • GitHub personal access tokens and fine-grained tokens for every developer or CI runner that shared a host with the infected packages.
    • npm publishing tokens for any account that has published or maintained the affected packages or any package in the same workspace.
    • Cloud provider API keys and service account credentials accessible from affected build environments.
    • SSH keys that lived on affected hosts, including keys baked into CI runners.
    • Any CI/CD secrets referenced by pipelines that ran on those hosts, including container registry credentials and signing keys.

    Rotation only helps if the new credentials are never exposed to the same compromised surface. Move secrets into a managed vault that the build pipeline pulls at runtime, not environment variables that persist on developer laptops.

    Why Official-Name Compromise Defeats Most Defenses

    Most dependency security tooling ranks risk by download count, maintainer reputation, and age. Every one of those signals pointed in the safe direction for the packages hit in this campaign. That is the lesson worth internalizing: an attacker who seizes a maintainer account inherits the maintainer’s trust score. The registry sees a legitimate upload from a known publisher, and every downstream consumer sees a familiar package name on a familiar version line.

    Sonatype’s 2025 State of the Software Supply Chain report put malicious open-source package uploads at roughly 200% year-over-year growth. The Mini Shai-Hulud campaign is consistent with that trend and shows it now reaching AI SDKs and frontend frameworks, the two ecosystems that ship code straight into production through automated publishing.

    Structural Defenses Worth Putting in Place

    Short-term cleanup matters, but the campaign also points to a set of structural controls worth adopting before the next incident.

    • Pin every dependency by exact version with an integrity hash, and treat lockfile drift as a security event, not a convenience.
    • Scope CI tokens to the narrowest permissions and shortest lifetimes the pipeline actually needs. Publishing rights should never live on the same token that runs tests.
    • Enable two-factor authentication on every package-manager account, including npm and PyPI, and prefer registry-supported trusted publishing over long-lived tokens.
    • Require signed commits and signed packages for any internal distribution channel that mirrors public packages.
    • Segment build environments so a compromised package cannot reach production secrets, cloud credentials, and the rest of the pipeline in a single hop.

    FAQ

    Which exact packages should I flag in my lockfiles?

    Six npm packages and one PyPI package. The npm names are @tanstack/react-router, @tanstack/history, @tanstack/router-core, @mistralai/mistralai, @mistralai/mistralai-azure, and @mistralai/mistralai-gcp. The PyPI name is mistralai at version 2.4.6.

    What are the file and network artifacts I should hunt for?

    Look for /tmp/transformers.pyz, pgmonitor.py, and pgsql-monitor.service on Linux hosts that may have imported or installed the affected packages. Also search logs for outbound traffic to 83.142.209.194 during the May 11 to May 12, 2026 window and after.

    If I find the payload file on a build runner, what is the right next step?

    Treat the host as fully compromised. Reimage it, rotate every secret that host could reach, and audit any artifact that pipeline produced after the install. Cleaning the filesystem is not sufficient because the credential theft has already happened.

    Related coverage

  • SpaceX-Cursor Acquisition: What a $60B AI Coding Deal Means for Your Stack

    SpaceX-Cursor Acquisition: What a $60B AI Coding Deal Means for Your Stack

    SpaceX announced Tuesday that it will acquire Cursor, the AI coding assistant, in an all-stock transaction valued at $60 billion. The deal folds Cursor’s model team into SpaceX’s Colossus supercomputer footprint and gives the aerospace company its first serious foothold in the developer-tools category for large language models. For site owners and technical teams already using AI-assisted coding, the merger changes who controls the toolchain and what risks come with it.

    What changed in the AI coding market overnight

    Cursor crossed $1 billion in annualized revenue by November 2025 and earned a place on the CNBC Disruptor 50 list. Behind that growth sat a ceiling the startup could not break on its own: compute availability. Cursor’s Composer model releases stalled repeatedly because the team could not secure enough training capacity. SpaceX removes that constraint by pairing Cursor’s product and research staff with infrastructure that venture-funded competitors cannot match.

    The acquisition also closes a gap in xAI’s lineup. OpenAI’s Codex, Anthropic’s Claude Code, and GitHub Copilot each have established developer communities. Cursor gives SpaceX a product developers already pay for, along with a team that has shipped coding-specific models at scale.

    How the deal is structured

    SpaceX formalized an option it secured in April, exercising it at the previously set $60 billion price. The structure matters for anyone watching market signals:

    • All-stock payment, representing roughly 3.4% dilution against SpaceX’s valuation at its public debut.
    • A $1.5 billion termination fee plus $8.5 billion in committed computing resources if the merger fails to close, a $10 billion floor for Cursor either way.
    • Cursor CEO Michael Truell will continue leading the team. He called the partnership a meaningful step on the path to building the best place to code with AI.

    That termination structure signals confidence on both sides. SpaceX is willing to hand over billions in compute even if regulators block the merger. Cursor locks in infrastructure access regardless of who owns it next quarter.

    The numbers that matter for technical decision-makers

    Five figures from the announcement carry practical weight:

    • $60 billion acquisition price, one of the largest AI startup transactions on record.
    • 3.4% dilution for SpaceX shareholders, calculated against the public-trading valuation that made SpaceX the fourth most valuable U.S. company.
    • $1.5 billion termination fee plus $8.5 billion in committed compute, a $10 billion floor for Cursor no matter how the deal resolves.
    • $1 billion annualized revenue for Cursor within three years of its 2022 founding.
    • Combined Thrive Capital exposure across both SpaceX and Cursor now valued above $10 billion.

    For teams evaluating Cursor, the floor commitment changes the calculus. Even in a regulatory block scenario, Cursor keeps access to SpaceX compute under contract. That reduces the supply-chain risk of betting on a startup model provider.

    What this means for developers auditing their own workflows

    If your team already relies on Cursor for inline editing, pull-request reviews, and terminal integration, expect two shifts. First, model iteration cycles should accelerate once Composer moves onto Colossus-class hardware. Larger context windows and stronger reasoning are the most likely early gains. Second, the platform may evolve into a fuller development environment designed for massive codebases, which changes how you structure prompts and review automation.

    If you do not use Cursor, the competitive pressure still reaches you. Anthropic now commands roughly half of the corporate spend on AI coding tools, according to spring 2026 outlay data, while Cursor’s share has receded from its earlier peak. A SpaceX-backed Cursor with cheaper compute can reset that pricing. Watch for revised seat tiers, new enterprise bundles, and possible bundling with other SpaceX or xAI products.

    What site owners and SEO teams should check now

    Consolidation at the model layer creates lock-in risk. A coding assistant baked into your CI pipeline, your content workflows, or your deployment scripts becomes a single point of failure when ownership changes. Review three areas before the deal closes in Q3 2026:

    • Vendor concentration. Map every tool in your stack that calls a frontier model API. Identify which ones depend on Cursor, Claude, or Codex specifically, and which can swap providers without code changes.
    • Data retention. Check the data-handling clauses in your Cursor agreement. A change of control can trigger renegotiation of training-data opt-outs and logging policies.
    • Pricing exposure. Lock in current enterprise rates before the merger, since post-close pricing typically resets toward the acquirer’s model.

    The risks worth pricing into your plan

    Model availability is not stable. The disruption around Claude Fable 5 showed that a coding tool’s underlying model can shift overnight, and any tool built on a frontier model inherits that volatility. SpaceX’s broader compute roadmap, including orbital AI data centers, hints at longer-term capacity growth, but also introduces new failure modes around latency, jurisdiction, and uptime SLAs that do not exist with terrestrial cloud providers.

    Regulators may also intervene. All-stock mergers between companies at this scale draw antitrust attention. The expected Q3 2026 close could slip if reviewers raise concerns, leaving Cursor in limbo during the transition.

    What to watch before Q3 2026

    Three signals will tell you how the integration is going. First, whether SpaceX routes Cursor under the xAI umbrella or keeps it as a standalone product, which determines branding and pricing. Second, the first major Composer release post-close, which will show whether compute access actually translates into measurable model gains. Third, any movement on Anthropic’s side, since Anthropic holds roughly half of the AI coding category’s corporate spend and will not cede share quietly.

    FAQ

    Why is SpaceX acquiring Cursor?

    SpaceX is buying Cursor to enter the AI coding assistance market, where OpenAI, Anthropic, and GitHub already have strong positions. The deal gives SpaceX a product with $1 billion in annualized revenue and a team that builds coding-specific models, backed by Colossus compute that Cursor could not access on its own.

    How much is the SpaceX-Cursor deal worth?

    The all-stock transaction values Cursor at $60 billion, roughly 3.4% dilution of SpaceX shares. If the merger does not close, SpaceX owes a $1.5 billion termination fee plus $8.5 billion in computing resources, a $10 billion floor for Cursor either way.

    When will the SpaceX-Cursor merger close?

    SpaceX expects the deal to close in the third quarter of 2026, pending regulatory approvals. Antitrust or other regulatory reviews could push the timeline back.

    Related coverage

  • Qwen3.6-27B Dense Model Beats Qwen3.5-397B-A17B on Coding Benchmarks

    Qwen3.6-27B Dense Model Beats Qwen3.5-397B-A17B on Coding Benchmarks

    Alibaba’s Qwen team has shipped Qwen3.6-27B, an open-weight dense transformer with 27 billion parameters that scores higher than its 397-billion-parameter Mixture-of-Experts predecessor, Qwen3.5-397B-A17B, across the four coding benchmarks that matter most to agent builders. On SWE-bench Verified, SWE-bench Pro, Terminal-Bench 2.0, and SkillsBench, the smaller model takes the lead. Released under Apache 2.0, the result changes what teams should expect to spend on serving capable code-generating AI in production.

    Why a 27B model beating a 397B model should change your audit checklist

    For most of the last two years, the safe assumption for technical teams planning capacity was: frontier coding accuracy requires a frontier-scale cluster. Mixture-of-Experts systems like Qwen3.5-397B-A17B activate only a slice of their parameters per token, but they still need multi-GPU nodes, careful sharding, and warm idle capacity to keep latency acceptable. A dense 27B model that matches or beats those systems on real software-engineering tasks breaks that assumption, which means several long-standing audit items deserve a second look.

    Self-host cost estimates that were written off as impractical for anything beyond a chatbot are now in range. Latency budgets sized for MoE inference paths can be re-checked against a simpler dense forward pass. Vendor lock-in reviews that justified proprietary coding assistants on accuracy grounds now need to weigh open-weight accuracy against API fees. Even observability coverage can shift: a model you run yourself exposes logs you actually own, which changes what you can capture in a privacy or compliance review.

    In short, the ceiling that pushed smaller models out of serious coding workloads is no longer there. Any site or platform that benchmarks, integrates, or competes with AI coding tools should re-test the assumptions behind those integrations.

    What is actually new in Qwen3.6-27B?

    Qwen3.6-27B is a pure dense transformer, meaning every parameter fires on every forward pass. That cuts the inference surface area in half compared with an MoE of comparable quality, removes the routing complexity that often surfaces as tail-latency spikes, and lets the model load with standard open-source serving stacks. There are no gating networks to profile, no expert-parallel layout to debug.

    The release ships as full open weights under Apache 2.0, which permits commercial use, modification, and redistribution with no royalty obligation. The team is distributing the model across four channels:

    • Open weights on Hugging Face and ModelScope
    • Qwen Studio, the team’s interactive chat and code playground
    • Alibaba Cloud Model Studio API for managed inference

    Qwen has not published detailed training-data recipes, but the gap over Qwen3.5-397B-A17B points to meaningful gains from data curation, instruction tuning, or targeted architecture changes aimed at agentic code workflows.

    How do the benchmark numbers stack up?

    Head-to-head figures from the official release show Qwen3.6-27B ahead on every coding benchmark tested:

    • SWE-bench Verified: 77.2% versus 76.2%
    • SWE-bench Pro: 53.5% versus 50.9%
    • Terminal-Bench 2.0: 59.3% versus 52.5%
    • SkillsBench: 48.2% versus 30.0%

    The SkillsBench gap is the widest: a dense 27B model scoring 48.2% against a 397B MoE system at 30.0% is a 18-point swing on a benchmark designed to measure practical software skills rather than synthetic test passes. For audit work, that kind of margin is large enough to treat the smaller model as a new baseline for any internal evaluation that has not been refreshed in 2026.

    What this means for developers and businesses running AI coding stacks

    For an indie developer or a small platform team, the practical upside is the ability to run state-of-the-art coding ability on a single GPU or a low-cost API tier. That removes per-token billing from the cost model for many internal tools, including code-review bots, repository Q&A systems, and PR-description generators. It also removes the data-egress concern that comes with sending private source code to a hosted vendor, which simplifies DPIA and vendor-risk paperwork.

    For larger teams, the story is infrastructure rather than line item. A dense 27B model runs on commodity accelerators with simpler topology than a 397B MoE, which lowers the floor on capital expenditure for any on-prem coding assistant build-out. It also opens the door to fine-tuning on private repositories without negotiating a separate enterprise contract.

    Three audit items are worth running again on the back of this release:

    • Re-baseline your coding assistant accuracy. If you last measured vendor performance in 2024 or early 2025, the gap to open-weight has likely closed.
    • Re-check self-host TCO. Pricing for single-GPU inference has dropped alongside model efficiency, so any “must be cloud-hosted” assumption may now be wrong.
    • Re-evaluate data residency. A model that runs in your own VPC changes what you can promise customers about where their code is processed.

    What to watch next

    Qwen has a track record of iterating quickly within a model family, so a reasoning-tuned or multimodal follow-up to Qwen3.6-27B is plausible. Community fine-tunes for specific languages, IDEs, and agent frameworks are also a near-certainty, given the Hugging Face ecosystem built up around earlier Qwen releases. Alibaba has indicated plans to integrate the model into its cloud-native AI services as a drop-in replacement for heavier coding assistants, which would put open-weight accuracy behind a managed endpoint for teams that prefer not to operate the serving stack themselves. Independent safety and red-team evaluations can begin the moment the weights land, since Apache 2.0 imposes no access restrictions.

    The bigger picture for technical teams

    The release reframes a debate that has dominated AI infrastructure planning since the first MoE coding models shipped: is scale the only reliable path to coding accuracy? A dense model roughly one-fifteenth the size of its MoE sibling, beating it on the hardest public coding benchmarks, is a clear counterexample. Better data curation, targeted tuning, and an open-release philosophy appear to extract more from fewer parameters than brute-force scaling alone. For any team planning AI capacity through 2026 and beyond, the lesson is to refresh assumptions often, because the floor on what a small model can do is moving quickly.

    FAQ

    What is Qwen3.6-27B?

    Qwen3.6-27B is an open-weight, 27-billion-parameter dense language model from Alibaba’s Qwen team. It targets code generation, debugging, and agentic software tasks and is released under Apache 2.0, which permits commercial and research use without royalties.

    How does Qwen3.6-27B compare to Qwen3.5-397B-A17B?

    On SWE-bench Verified, SWE-bench Pro, Terminal-Bench 2.0, and SkillsBench, Qwen3.6-27B scores higher than Qwen3.5-397B-A17B despite having 27 billion parameters against the MoE model’s 397 billion total. The published deltas are 77.2% versus 76.2%, 53.5% versus 50.9%, 59.3% versus 52.5%, and 48.2% versus 30.0%.

    Where can you access Qwen3.6-27B?

    The weights are hosted on Hugging Face and ModelScope, the team offers an interactive demo called Qwen Studio, and Alibaba Cloud provides a managed inference endpoint through Model Studio API.

  • OpenAI Puts $150M Behind a New Partner Network to Ship Enterprise AI

    OpenAI Puts $150M Behind a New Partner Network to Ship Enterprise AI

    OpenAI has stood up a global Partner Network seeded with $150 million and a target of certifying 300,000 consultants by the end of 2026. Founding partners include Accenture, Bain, BCG, McKinsey, and PwC, joined by technology specialists Eliza and Artium. The program is built around tiered certifications, product specializations, and closer alignment with OpenAI’s own deployment teams.

    For anyone running technical SEO audits, the network matters because the bottleneck in enterprise AI has moved from model quality to last-mile integration: connecting frontier models to payroll, CRM, customer service, and supply chain systems. That shift changes which procurement questions buyers ask, which vendors show up in RFPs, and how quickly AI features land on the public-facing pages you audit.

    What changed for enterprise buyers

    Large organizations have spent the last two years running pilots that rarely scale. McKinsey’s annual global AI studies have repeatedly shown that a wide majority of firms experiment with generative AI, while only a small fraction push those projects into production. OpenAI’s bet is that a curated partner roster can close that gap by packaging model access with workflow redesign and change management.

    The procurement picture changes too. Instead of evaluating a consultancy on a slide deck, enterprise teams will eventually be able to filter candidates by tier and by earned specializations. A partner that has cleared the bar for Codex, cybersecurity, or agents carries a different weight in a vendor review than one that has not.

    How the tiering and specializations work

    The network runs on a three-tier ladder: Select, Advanced, and Elite. Movement between tiers is gated by documented performance in four areas: sales, technical delivery, co-selling with OpenAI, and customer deployment experience. The intent is to make the tiers a credible signal rather than a paid badge.

    On top of the tiers, partners can earn specializations in domains where OpenAI wants deep, repeatable expertise. Codex, cybersecurity, and agents are the first three. The specialization track is where most of the practical value sits for buyers, because a generic AI partner is rarely what a regulated workload needs.

    The Forward Deployed Experts pilot

    Alongside the tier structure, OpenAI is launching a Forward Deployed Experts pilot. Selected partner practitioners get embedded with OpenAI’s Forward Deployed Engineering teams on the hardest enterprise builds. The expected payoff is that playbooks and product knowledge developed inside OpenAI migrate outward into partner delivery teams, shortening the time between contract signature and a working production system.

    For sites and products that consume these deployments, the pilot is a marker of where the most ambitious integrations will land first: complex, high-stakes environments where a half-finished rollout is not an option.

    What this looks like in a real deployment

    The first wave of joint work is already shipping. eBay worked with Artium and OpenAI to build a next-generation AI customer service platform that pairs AI agents with human agents. Dan Leiva, Vice President of Customer Service and Marketing Technology at eBay, described the result: eBay collaborated with Artium and OpenAI to develop a customer service platform designed to enhance experiences for both customers and customer service teams, setting a new standard in customer care where human expertise and AI agents work together to deliver faster, more consistent, and more personalized resolutions.

    That pattern, model plus specialist integrator plus a clear operational use case, is the template the network is designed to repeat at scale.

    What to watch as the network ramps

    Three signals will tell you whether the program is producing real outcomes or just press releases.

    • The specialization catalog will widen as OpenAI ships new products. Track which badges appear and how many partners earn them, because density of specialized partners is a proxy for how mature each product line is in the field.
    • The Forward Deployed Experts pilot will either expand or stall. Expansion means OpenAI is confident enough in partner delivery to put its own engineers on joint projects; a stall means the integration story is still rougher than the marketing suggests.
    • The 300,000-consultant target is aggressive. Progress toward it is a leading indicator of how much AI delivery capacity enters the mid-market, where most companies sit today.

    What this means if you audit sites that ship AI features

    If your client roster includes products that embed generative AI, the partner network reshapes the integration roadmap and, by extension, the pages you need to audit.

    • Expect faster rollouts of AI features on customer-facing surfaces. As partner capacity grows, feature velocity on product pages, help centers, and transactional flows will increase, and so will the surface area for SEO regressions.
    • Watch for new vendor stacks in your clients’ tech inventories. Integrations built through Elite-tier partners tend to show up in render-blocking scripts, chatbot embeds, and structured data that search engines interpret as site quality signals.
    • Track changes to how AI-assisted content is disclosed. Regulated deployments, especially in finance and healthcare, are the natural early adopters of partner-led rollouts, and disclosure norms are still being written.

    The headline for auditors is simple. The model layer is becoming a commodity, and the differentiation is moving into how AI gets wired into real products. Your audit checklist has to move with it: integration footprint, vendor concentration, render performance of AI embeds, and the discoverability of any AI-generated content that ships to public URLs.

    FAQ

    What is the OpenAI Partner Network?

    The OpenAI Partner Network is a global program launched with a $150 million investment, aimed at certifying 300,000 consultants by the end of 2026. Founding partners include Accenture, Bain, BCG, McKinsey, PwC, Eliza, and Artium.

    How is OpenAI structuring partner tiers and specializations?

    Partners progress through Select, Advanced, and Elite tiers based on sales performance, technical capability, co-sell engagement, and delivery experience. They can also earn specializations in Codex, cybersecurity, and agents.

    What is the Forward Deployed Experts pilot?

    Forward Deployed Experts is a pilot program that places qualified partner practitioners alongside OpenAI’s Forward Deployed Engineering teams on complex enterprise deployments, with the goal of transferring OpenAI’s internal playbooks and product knowledge into partner delivery work.

  • Update or Create? A Practical AEO and GEO Audit Framework for 2026

    Update or Create? A Practical AEO and GEO Audit Framework for 2026

    AI search platforms such as Google AI Overviews, ChatGPT Search, and Perplexity do not list ten blue links the way classic search engines once did. They generate a single answer and cite the pages behind it. For anyone running a technical SEO audit in 2026, every URL on a site now carries a binary question: refresh the page so it gets cited, or retire it and build something new. The framework below covers the signals to check, the order to check them in, and the structural fixes that move a page from invisible to cited.

    Why refresh beats replacement for most pages

    AI search uses Retrieval-Augmented Generation (RAG) to pull live data from search indexes before composing an answer. When an existing URL is updated, RAG reprocesses only the changed content, and the page keeps the backlinks, entity associations, and crawl trust it already earned. A brand-new URL starts at zero on all three counts and often waits weeks or months before it is cited at all. That gap is the central reason an audit should default to refresh before recommending new content.

    The default flips only when the existing page is structurally unsalvageable, targets a query cluster the site has never covered, or carries penalties that block indexing regardless of content quality.

    AEO versus GEO: what each audit pass measures

    Answer Engine Optimization (AEO) and Generative Engine Optimization (GEO) are two layers of the same goal. Separating them during an audit prevents common fixes from being skipped.

    • AEO checks focus on extractability. Is there a direct answer inside the first 100 words? Does the page use FAQ or HowTo schema? Do headings mirror the questions real users type, or do they read like internal labels?
    • GEO checks focus on citability. Does the page carry original data, named expert contributions, or first-party research? Are claims sourced to credible references an AI model can verify? Is the topic coverage deep enough that the model would pick this page over a competitor when synthesizing a response?

    A page can pass AEO and still never get cited because it lacks GEO signals. An audit that scores both layers separately produces clearer fix lists.

    Which pages to refresh first during an audit

    Not every URL warrants the same effort. Sorting URLs by the signals below produces a ranked worklist the audit can hand to a content team.

    • Top priority: URLs ranking in positions 11 through 20 (the bottom of page 1 through the top of page 2) with referring domains above the site’s median. These pages already carry authority and need only structural lift to move into AI citation territory.
    • High priority: URLs with steady Search Console impressions but a falling click-through rate. A drop in CTR while impressions hold usually means the title or the opening answer no longer matches intent, which a targeted refresh often reverses in a single cycle.
    • High priority: URLs with more than 100 referring domains that return no AI citations when checked in Perplexity, ChatGPT Search, or Google AI Overviews for their target query. The authority exists; the structure is failing.
    • Lower priority: thin URLs with no traffic and weak backlink profiles. These are usually better candidates for consolidation into a stronger pillar page than for a standalone refresh.

    What to verify on each page before recommending a refresh

    A refresh recommendation should not leave the audit stage as a vague instruction. Tie it to specific checks:

    • Direct answer present in the first 100 words, phrased as a complete response rather than a question.
    • Headings rewritten as real user questions, with each question answered immediately beneath it.
    • FAQ or Article schema present, validated, and matching the visible content rather than placeholder copy.
    • Statistics and examples updated to the current calendar year, with sources linked inline.
    • Internal links refreshed to point at newer pillar content rather than orphaned pages.
    • Canonical tag, robots directives, and hreflang still aligned with the live URL.

    When a new page is the right audit outcome

    Net-new content earns its keep only when at least one of these conditions is true during the audit:

    • The topic is absent from the site’s content library and has measurable search demand.
    • The existing page targets a fundamentally flawed premise, such as a deprecated product, an outdated regulation, or a query whose intent has shifted entirely.
    • The keyword cluster cannot be folded into an existing URL without diluting that page’s primary topic, which would hurt GEO signals.

    If none of these conditions apply, the audit should recommend consolidation: merge overlapping posts into a single pillar page, redirect the old URLs, and preserve the referring domains those URLs carry.

    How freshness signals feed back into the audit cycle

    Google’s own SEO documentation notes that more recent content can be more relevant for queries where freshness matters, and that updating a page can improve its quality. Translated into audit practice, freshness is a relevance signal AI systems read alongside backlinks and entity data. A site that updates its priority pages on a 30 to 90 day cadence builds a record of active maintenance that AI platforms treat as a trust signal, which raises the odds those pages surface in knowledge panels and generated responses.

    The practical cadence for most sites:

    • Quarterly refresh of top-priority URLs.
    • Immediate update of any page affected by a major industry event, product change, or regulatory shift.
    • Annual full-site audit with AEO and GEO scoring applied to every indexed URL.

    Running the framework against a single page

    Take a service page that ranks on page 2 with 45 referring domains and no citations in ChatGPT Search. The audit pass walks the checklist:

    1. AEO layer: confirm a direct answer sits in the opening paragraph, rewrite headings as questions, add FAQ schema that matches the visible Q&A block.
    2. GEO layer: add first-party data (a customer count, a measured outcome, a process diagram), cite an industry source by name, and link to a relevant internal pillar piece.
    3. Structural layer: validate canonical, check Core Web Vitals, confirm the page renders the FAQ block without requiring JavaScript that crawlers may not execute.

    If all three layers pass after the refresh, the page returns to monitoring. If the GEO layer cannot be completed because the topic is too thin to support expert claims, the audit recommendation flips to consolidation rather than another refresh cycle.

    Common audit findings and their fixes

    • Direct answer buried past the 100-word mark: rewrite the opening paragraph so the core claim lands in the first two sentences.
    • Headings labeled like internal categories (Services, About, Details): rewrite each as a question the target audience actually searches.
    • Schema present but mismatched: regenerate FAQ or Article schema from the live content rather than reusing a template from another page.
    • Statistics older than two years: replace with current-year data sourced to a named provider, and update the visible publication date where the content meaningfully changed.
    • Multiple URLs targeting the same query cluster: pick the strongest URL, redirect the rest, and confirm the canonical chain is clean.

    FAQ

    What is the difference between AEO and GEO in an SEO audit?

    AEO (Answer Engine Optimization) measures how easily an AI assistant or featured snippet can extract a direct answer from a page, which depends on factors like a concise answer in the first 100 words, FAQ or HowTo schema, and question-form headings. GEO (Generative Engine Optimization) measures whether a page is likely to be chosen as one of the sources an AI model synthesizes when generating a full reply, which depends on authority signals such as original data, named expert contributions, and thorough topic coverage. Both layers need to pass for a page to be cited consistently.

    How often should priority pages be refreshed for AI search visibility?

    High-impact pages, including URLs ranking in positions 11 to 20 and key product or service pages, benefit from a refresh every 30 to 90 days. Any page affected by a major industry event, a product change, or a regulatory update should be revised as soon as the change is public. A full audit with AEO and GEO scoring across every indexed URL should run at least once a year so structural decay is caught before it costs citations.

    Does updating an existing URL produce AI citations faster than publishing a new page?

    In most cases, yes. An updated URL keeps the backlinks, entity associations, and crawl trust it already accumulated, which lets Retrieval-Augmented Generation systems incorporate it into generated answers much sooner. A new URL has to be crawled, indexed, and assigned a trust score before it can be cited, and that delay often runs into weeks or months. Net-new pages should be reserved for topics the site has not covered, queries with no existing URL that can serve them, or pages that are too thin to salvage with a refresh.

    Related coverage

  • Survey: 60% of U.S. Consumers Find AI in Brand Messaging a Turnoff

    Survey: 60% of U.S. Consumers Find AI in Brand Messaging a Turnoff

    Six in 10 U.S. consumers say the term AI in a brand’s messaging is a turnoff, and 86% still want to check the original source before trusting what an answer engine tells them. Those are the headline numbers from a new field study of 2,000 U.S. adults and business leaders, run in April 2026, and they carry direct implications for anyone auditing a site for AI search visibility.

    The contradiction is sharp: 60% of enterprise respondents reported that traffic from AI search platforms has climbed over the past year, and 74% now call AI discoverability a main or significant priority. At the same time, the same share of consumers (60%) read AI labels in marketing copy as a signal to disengage. Brands chasing citations are running headlong into audiences that distrust the very word they are leaning on.

    What the study measured

    The April 2026 survey split its 2,000 respondents into 1,200 general consumers and 800 enterprise CMOs and decision-makers. The dual sample lets the report compare what buyers want against what publishers are investing in, and the gap is the story. Enterprises are betting budget on being cited by AI; consumers are paying more attention, not less, to whether a real person stands behind a page.

    Brian Alvey, CTO of WordPress VIP, framed the tension in the report: brands must now build sites that are legible to AI agents acting on behalf of people, and still feel trustworthy to the small slice of users who actually click through past the answer box. Failing either side means losing either the citation or the repeat visitor.

    The trust signals that actually move the needle

    The survey asked consumers what makes an AI-mediated page feel credible. The answers were concrete and actionable for site owners:

    • 33% rank clicking through to the original source as their top trust signal, ahead of known brand reputation.
    • 86% do not fully trust AI-generated answers and want to verify primary sources themselves.
    • 42% rank unattributed AI responses as less trustworthy than airline fees, confusing privacy policies, or a medical bill.
    • 73% feel the internet is less human than it was a decade ago.
    • 80% believe web information should stay openly accessible, rather than sitting behind a small number of walled platforms.

    Each of those numbers maps to something a technical SEO audit can check. Original-source visibility, attribution markup, open access, and the human voice in copy are all reviewable on a page-by-page basis.

    What to audit on your own pages

    Site owners can use the survey results as a checklist for content that needs to earn both a citation and a click.

    Source attribution on every claim

    If a third of consumers treat the outbound source link as their primary trust check, that link needs to be visible, descriptive, and loadable by crawlers. Audit body content for inline citations, anchor text that names the source, and any claims that lack a verifiable reference. Pages with statistics, quotes, or product claims should link to a primary document, not a roundup post.

    Structured data for authorship and provenance

    Schema markup for author, organization, and datePublished helps answer engines connect a claim to a real entity. Run a crawl and confirm that author markup is present on editorial content, that the author entity resolves to a real profile page, and that the same author name is consistent across posts. Inconsistent or missing authorship is a quiet trust leak that the 33% figure makes expensive.

    Open access for high-value pages

    80% of respondents want information to stay freely accessible, and AI agents will follow that preference. Pages blocked by paywalls, login walls, or aggressive consent interstitials can be parsed less reliably and cited less often. Audit your top cited URLs to confirm they render fully for unauthenticated crawlers and do not require a click-through before content loads.

    The AI label problem in copy

    60% of consumers are put off by the word AI in marketing language. That means a page lead or product page that opens with AI-powered, AI-driven, or intelligent automation as the headline framing may lose engagement before the value prop lands. Run a content scan for the label across landing pages, hero copy, meta descriptions, and social bios. Replace AI-first framing with benefit-first framing, and reserve technical AI references for product documentation where buyers expect them.

    Human voice in the body text

    73% of consumers say the web feels less human than a decade ago. That is partly a writing problem, not a tooling problem. Audit recent posts for signs of templated boilerplate: generic intros, repeated transition phrases, listicles with no original analysis. Pages that read like model output will underperform on the trust side of the AI search equation even if they rank.

    What enterprise teams are signaling

    On the publisher side, 60% of enterprise respondents saw AI-referred traffic grow over the past year, and 74% treat AI discoverability as a main or significant priority. That gap between buyer skepticism and publisher investment is the engine driving the next round of changes: provenance labels, verified-source badges, and richer attribution formats similar to the credit lines already common in voice assistants. Sites that invest in clean bylines, original research, and open citation practices now will be the easiest for platforms to label as trustworthy later.

    The bigger signal

    The 2025 Edelman Trust Barometer special report on AI put global trust in artificial intelligence at 33%, and the WordPress VIP numbers suggest U.S. consumer sentiment has hardened further since. For SEO and content teams, the practical lesson is to stop treating AI optimization and human credibility as separate workstreams. Citation-ready content, transparent sourcing, and a clear human voice are the same checklist. Pages that pass it will earn both the answer-engine mention and the click that follows.

    FAQ

    Why are consumers turned off by the word AI in brand messaging?

    The April 2026 survey of 2,000 U.S. adults found 60% say the label AI in a brand’s messaging is a turnoff, while 86% do not fully trust AI-generated answers and 73% feel the internet is less human than it was ten years ago. The label reads as automation without accountability, and buyers are responding by discounting it.

    How much do consumers trust AI-generated answers without source attribution?

    42% of respondents rank unattributed AI answers as less trustworthy than airline fees, confusing privacy policies, or a medical bill. 86% want to verify primary sources themselves, and 33% point to clicking through to the original source as their single strongest trust signal.

    Can brands use AI for content without losing audience trust?

    The survey does not penalize AI used behind the scenes. It shows consumers react to AI being marketed to them as a feature. Brands that use AI for research or drafting, keep human review in the loop, and publish with visible authorship and source links can stay efficient without triggering the 60% turnoff response.